Top 100 IA · France
Maxime Labonne
Liquid AI 
- Score
- 7 473+14 auj.
- Rang
- 61/198 ↓6
- sur 90 jours
- +157+2,0 %
Maxime Labonne est un scientifique spécialisé en Machine Learning, expert des modèles de langage à grande échelle (LLM) et des réseaux neuronaux graphiques. Titulaire d'un doctorat de l'Institut Polytechnique de Paris, il est reconnu comme Google Developer Expert en IA/ML. Labonne a développé plusieurs LLM populaires, dont AlpahMonarch-7B, Beyonder-4x7B, Phixtral et NeuralBeagle14, ainsi que des outils comme LLM AutoEval et LazyMergekit.
Données au 25 oct. 2026.
Les chiffres bruts · 90 derniers jours
- Vues médianes
- 39,7 k
- par publication
- Interactions médianes
- 496
- par publication
- Publications
- 96
- sur 90 jours
- Abonnés
- 120,4 k
- tous réseaux scorés
Ce qui fait le score
Centiles 0 – 100 face à tous les créateurs suivis.
- Portée · 30 %85
Vues moyennes par publication sur 90 jours
- Engagement · 30 %72
Réactions moyennes par publication
- Audience · 30 %74
Abonnés cumulés, rapportés à la population
- Régularité · 10 %100
Rythme de publication (25 posts / 90 j = 100)
Réseaux
120,4 k abonnés cumulés
| Réseau | Abonnés | Score |
|---|---|---|
| X@maximelabonne | 45,1 k | 8 010t2 |
| LinkedIn@maxime-labonne | 75,3 k | 11 190t1 |
30 derniers jours
Les meilleurs posts de Labonne
 LinkedIn · il y a 28 j#1ML
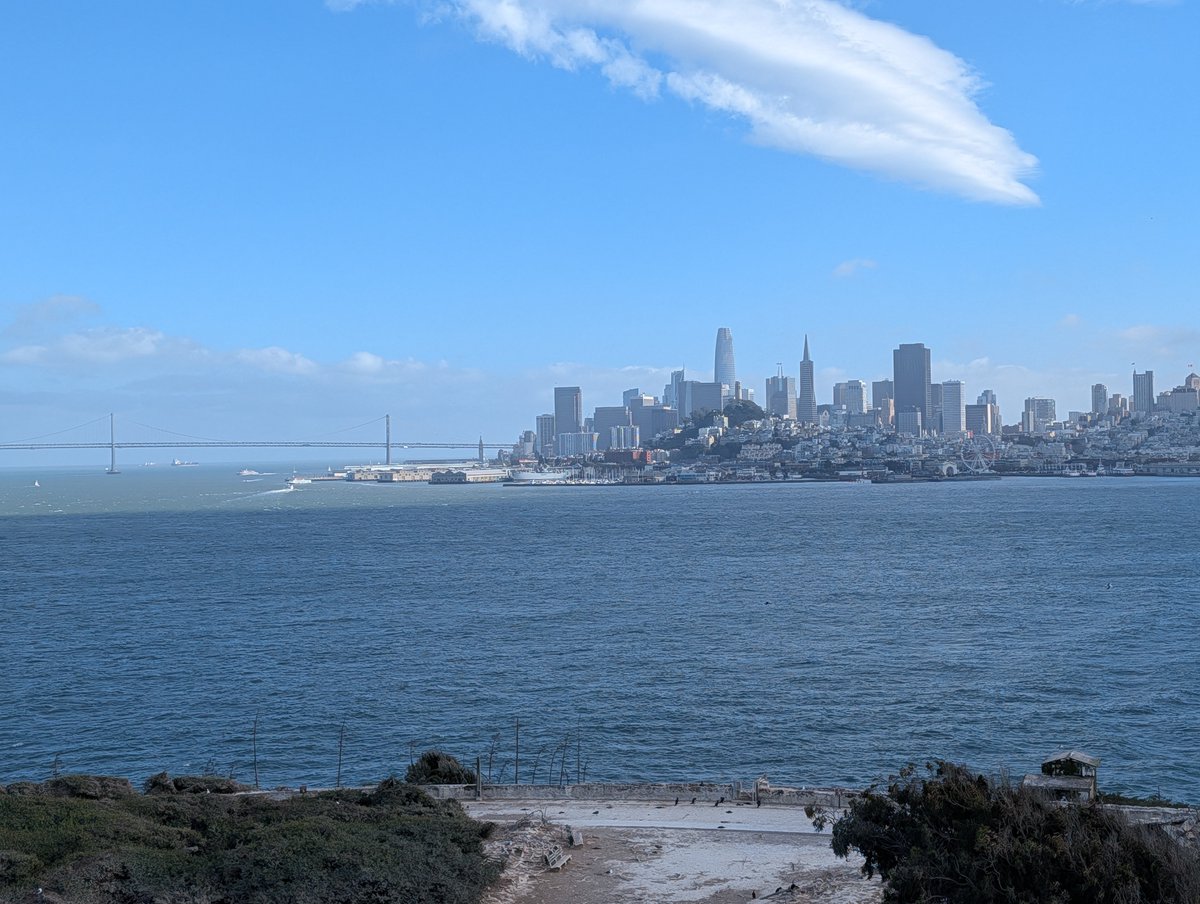
Goodbye London, hello San Francisco Life update: I moved to SF (with Liquid AI). It's quite nice to have an office after being fully remote for over two years. So far, the city is really pretty and the weather is actu…
80,8 k vues1,1 k interactions
 LinkedIn · il y a 7 j#2ML
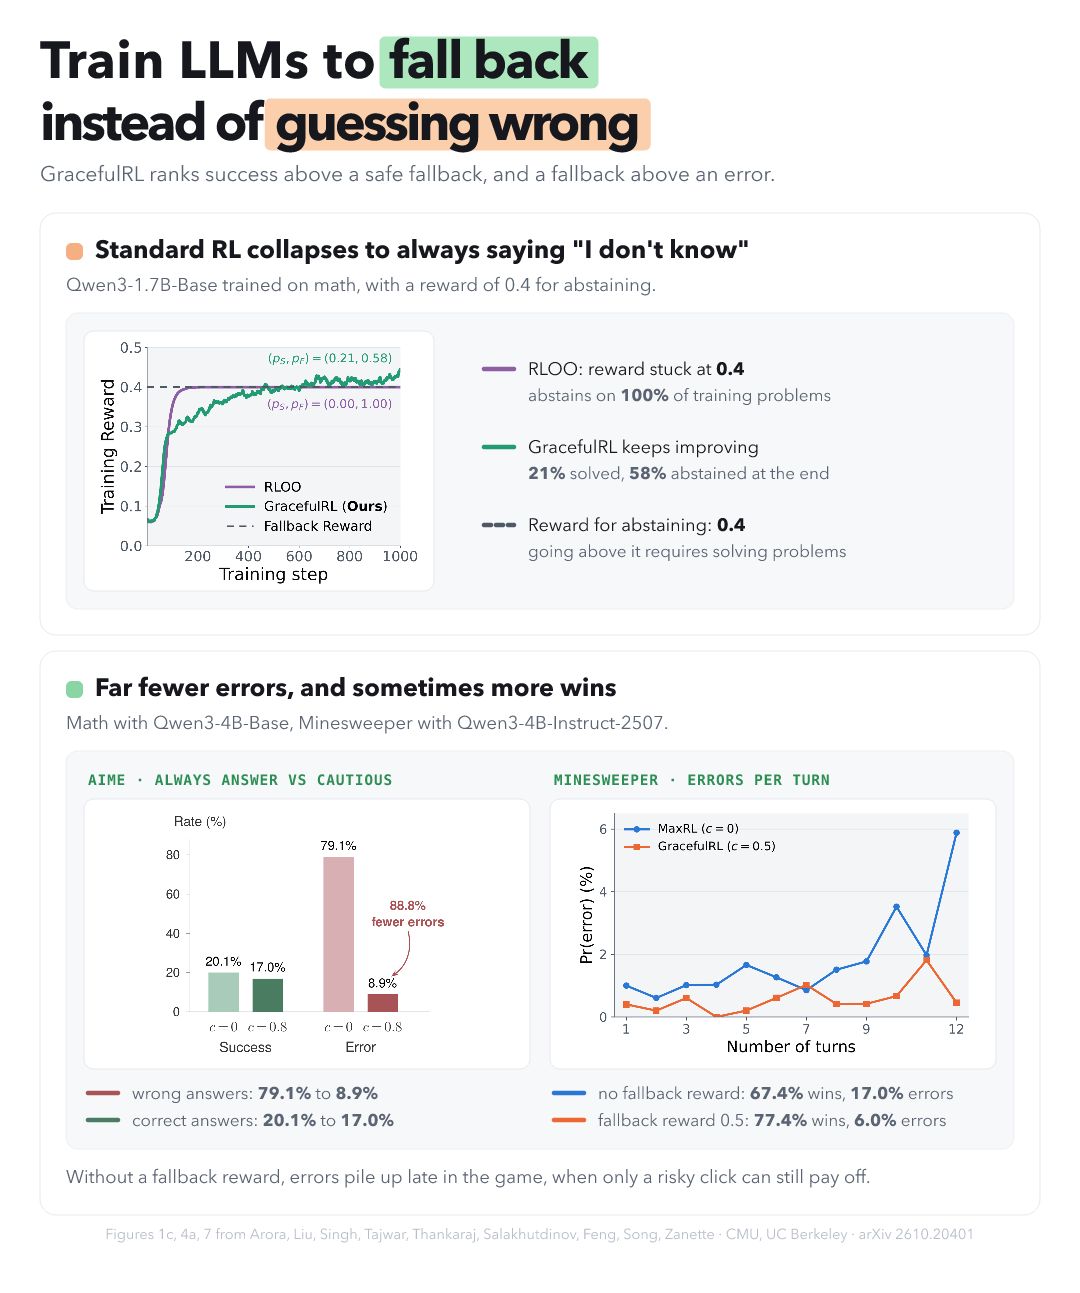
Can you train an LLM to say “I don’t know” without it saying it all the time? With reinforcement learning with verifiable rewards (RLVR), a model is rewarded for answering correctly. Saying "I don't know" is typically…
53,7 k vues671 interactions
 LinkedIn · il y a 13 j#3ML
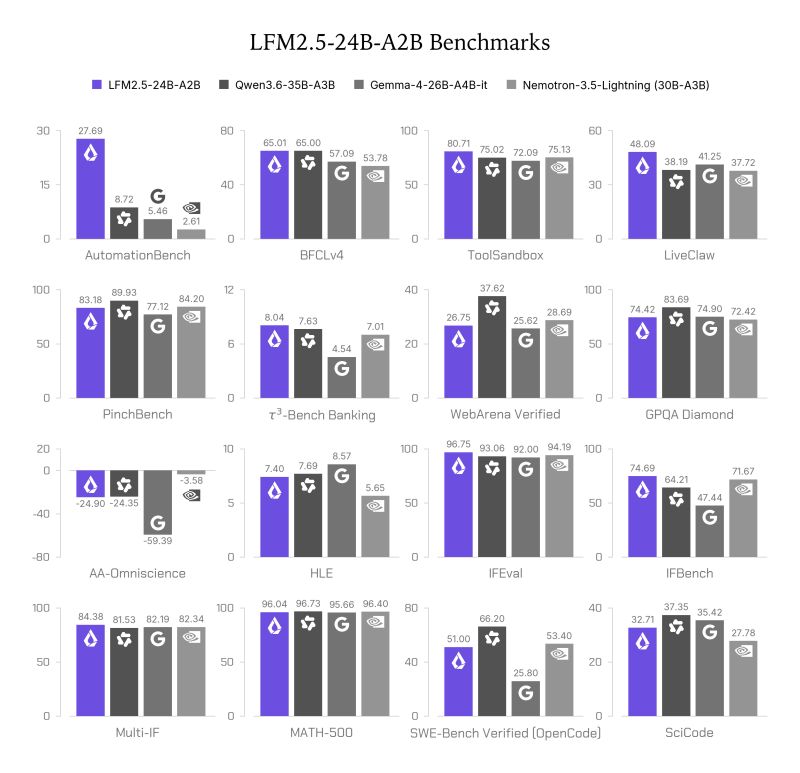
We just released LFM2.5-24B-A2B! 🥳 It's an extremely fast agentic model, competitive with models with 50% more parameters. We expanded the context window to 131k and training up to 36T tokens. On the post-training si…
53,1 k vues661 interactions
- X · il y a 24 j#4
Great read: SFT generalizes worse than RL because the data is off-policy, not because of the SFT objective. Rewriting the trajectories from an expert to look like what the base model writes can match or beat on-policy…
ML41,9 k vues620 interactions
 X · il y a 28 j#5ML
Life update: goodbye London, I moved to SF (still with @liquidai) 🫡 Let's grab coffee? https://t.co/bVgoyT9zJR
16,6 k vues481 interactions
 LinkedIn · il y a 3 j#6ML
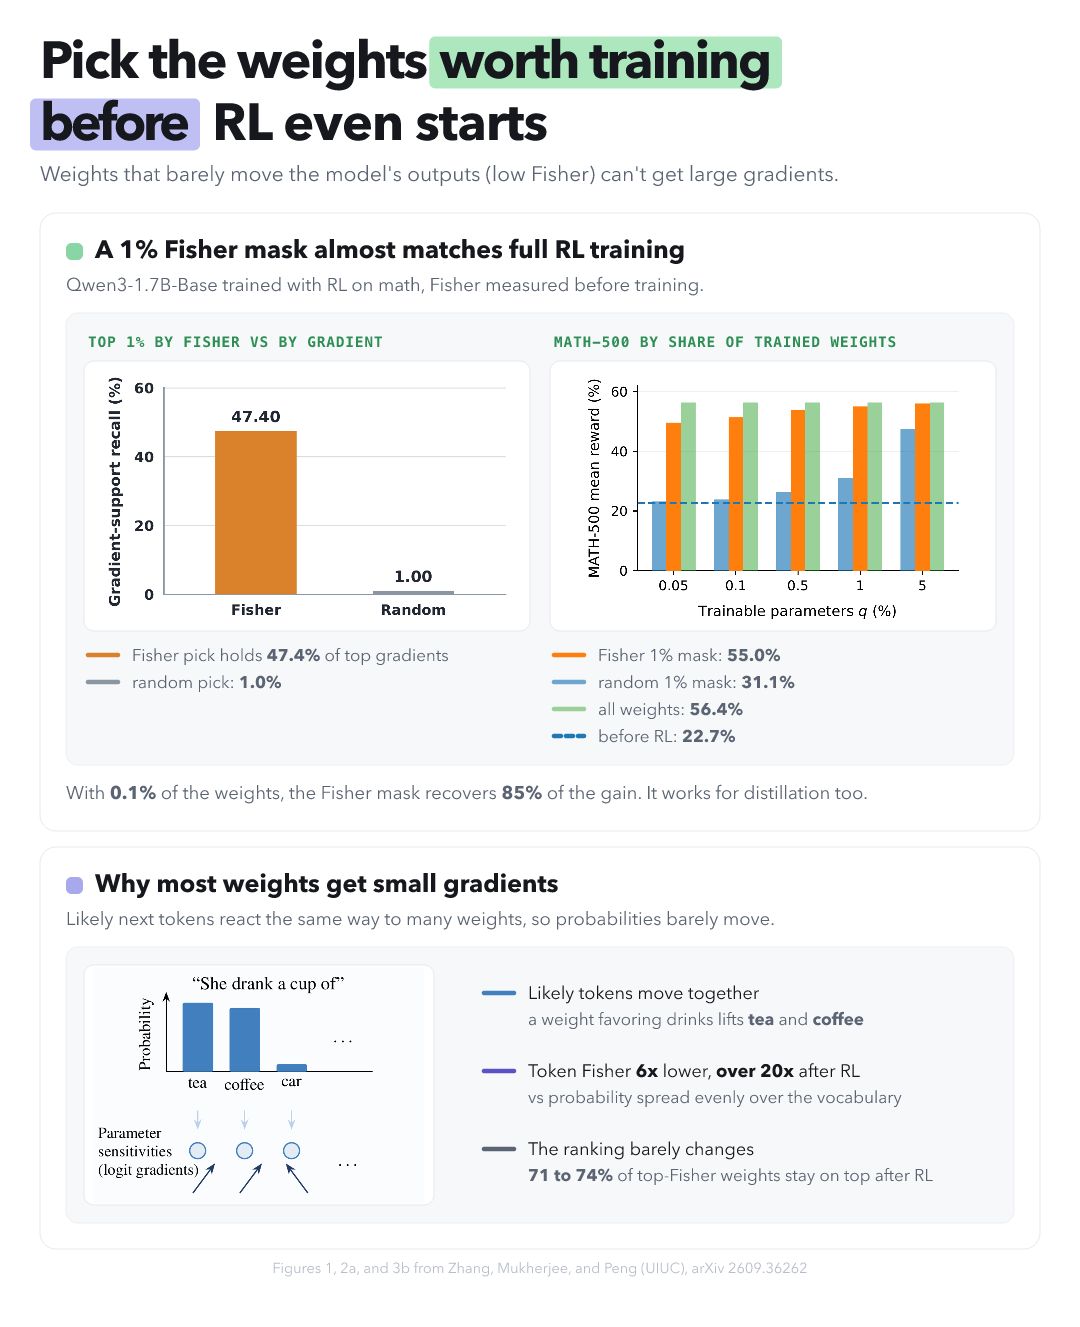
Understanding LLM Parameter Update Sparsity through the Lens of Fisher It's a cool paper that offers a competing explanation to the traditional "RL's updates are low rank because you get about 1 bit of information per…
32,6 k vues389 interactions
Face-à-face