Top 100 IA · Bulgaria
Georgi Gerganov
ggml 
- Punteggio
- 7201+1 oggi
- Posizione
- 77/198 ↓7
- in 90 giorni
- +338+4,6%
Georgi Gerganov è un fisico e programmatore noto per i suoi contributi alla tecnologia open-source e ai progetti di programmazione. Si concentra sullo sviluppo e sulla promozione di strumenti come llama.cpp, che consentono un'inferenza AI locale efficiente. I suoi contenuti includono principalmente tutorial tecnici, dimostrazioni software e aggiornamenti sulle integrazioni di modelli AI, spesso collaborando con organizzazioni come Hugging Face e NVIDIA.
Dati al 26 ott 2026.
I numeri grezzi · ultimi 90 giorni
- Visualizzazioni mediane
- 49,6K
- per post
- Interazioni mediane
- 673
- per post
- Post
- 14
- in 90 giorni
- Follower
- 81K
- tutti i social nel punteggio
Cosa determina il punteggio
Percentili 0 – 100 rispetto a tutti i creator monitorati.
- Portata · 30%87
Visualizzazioni medie per post su 90 giorni
- Engagement · 30%77
Reazioni medie per post
- Audience · 30%66
Follower totali, rapportati alla popolazione
- Costanza · 10%75
Ritmo di pubblicazione (25 post / 90 g = 100)
Social
81K follower in totale
| Social | Follower | Punteggio |
|---|---|---|
| YouTube@Georgi Gerganov | 3,4K | 267t10 |
| X@ggerganov | 73,5K | 8362t2 |
| LinkedIn@georgi-gerganov-b230ab24 | 4,1K | 837t10 |
Ultimi 30 giorni
I migliori post di Gerganov
- X · 25 gg fa#1
Decision models in llama.cpp are now available The `/v1/systemone` endpoint is available in the latest llama builds. Use it to do Jev-style inference locally, efficiently and privately. Multiple open models are suppor…
GGGeorgi Gerganov116,4K visualizzazioni2,4K interazioni
- X · 22 gg fa#2
The new v0.6.0 release packs a lot of good stuff: - Clef support (text + vision) - High-quality support for Qwen3.8-Flash-Next - Massive performance improvement with Metal - New `llama_batch_ext` API Also the website …
GGGeorgi Gerganov111,6K visualizzazioni933 interazioni
- X · 21 gg fa#3
If you are using Qwen3.8-27B + MTP, make sure to upgrade to DFlash for extra speed: llama serve -hf ggml-org/Qwen3.8-27B-GGUF --spec-type draft-dflash --spec-draft-n-max 7 Requires the latest llama.cpp v0.6.0
GGGeorgi Gerganov43,5K visualizzazioni874 interazioni
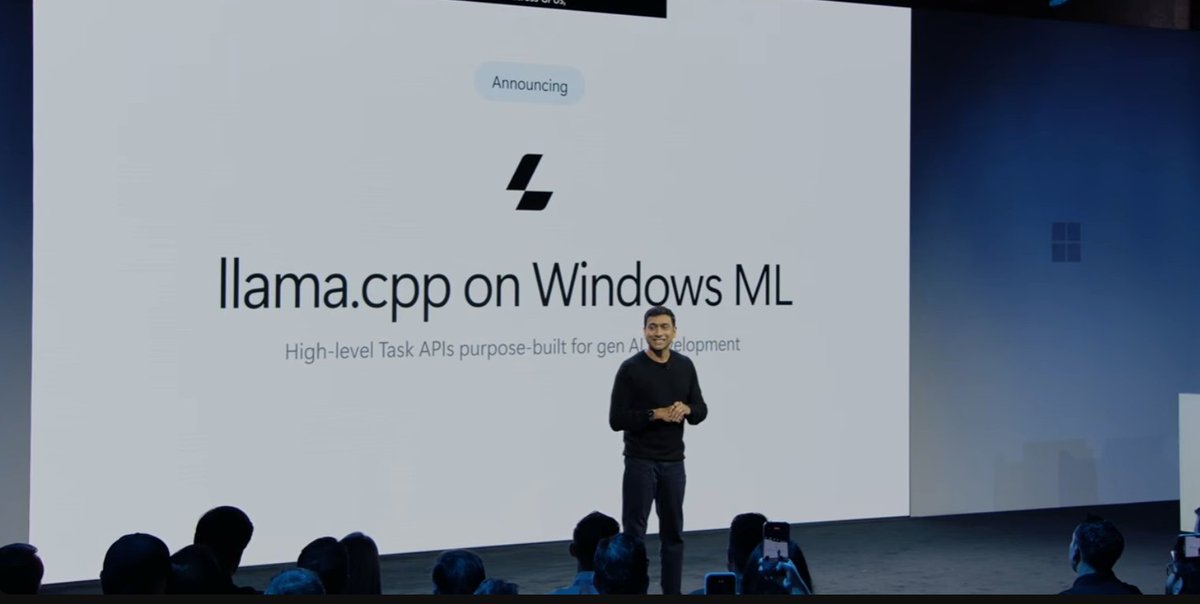 X · 20 gg fa#4GGGeorgi Gerganov
It is very cool to see llama.cpp on the big stage in todays Windows event! The software and hardware stacks are finally coming together. Our community has put a lot of hard work in the past years and it shows. Looking…
34K visualizzazioni767 interazioni
- X · 21 gg fa#5
Day-0 support for EmbeddingGemma 2 in llama.cpp https://t.co/Gi4I3RNSXc
GGGeorgi Gerganov26,4K visualizzazioni703 interazioni
- X · 20 gg fa#6
llama.cpp can distribute inference on heterogeneous devices through the ggml RPC backend It's an advanced setting but I think with time we'll make it more accessible to regular users.
GGGeorgi Gerganov25,5K visualizzazioni532 interazioni
Faccia a faccia