Top 100 AI · Bulgaria
Georgi Gerganov
ggml 
- Score
- 7,2000 today
- Rank
- 76/198 ↓6
- over 90 days
- +337+4.6%
Georgi Gerganov is a physicist and programmer known for his contributions to open-source technology and programming projects. He focuses on developing and promoting tools like llama.cpp, which enable efficient local AI inference. His content primarily includes technical tutorials, software demonstrations, and updates on AI model integrations, often collaborating with organizations like Hugging Face and NVIDIA.
Data as of Oct 25, 2026.
The raw numbers · last 90 days
- Median views
- 49.5K
- per post
- Median engagements
- 673
- per post
- Posts
- 14
- over 90 days
- Followers
- 81K
- all scored platforms
What drives the score
Percentiles 0–100 against all tracked creators.
- Reach · 30%87
Average views per post over 90 days
- Engagement · 30%77
Average reactions per post
- Audience · 30%66
Total followers, relative to population
- Consistency · 10%75
Posting frequency (25 posts / 90 days = 100)
Platforms
81K total followers
| Platform | Followers | Score |
|---|---|---|
| YouTube@Georgi Gerganov | 3.4K | 267t10 |
| X@ggerganov | 73.5K | 9,615t1 |
| LinkedIn@georgi-gerganov-b230ab24 | 4.1K | 836t10 |
Last 30 days
Gerganov's top posts
- X · 24 days ago#1
Decision models in llama.cpp are now available The `/v1/systemone` endpoint is available in the latest llama builds. Use it to do Jev-style inference locally, efficiently and privately. Multiple open models are suppor…
GGGeorgi Gerganov116.3K views2.4K engagements
- X · 21 days ago#2
The new v0.6.0 release packs a lot of good stuff: - Clef support (text + vision) - High-quality support for Qwen3.8-Flash-Next - Massive performance improvement with Metal - New `llama_batch_ext` API Also the website …
GGGeorgi Gerganov111.6K views933 engagements
- X · 20 days ago#3
If you are using Qwen3.8-27B + MTP, make sure to upgrade to DFlash for extra speed: llama serve -hf ggml-org/Qwen3.8-27B-GGUF --spec-type draft-dflash --spec-draft-n-max 7 Requires the latest llama.cpp v0.6.0
GGGeorgi Gerganov43.5K views874 engagements
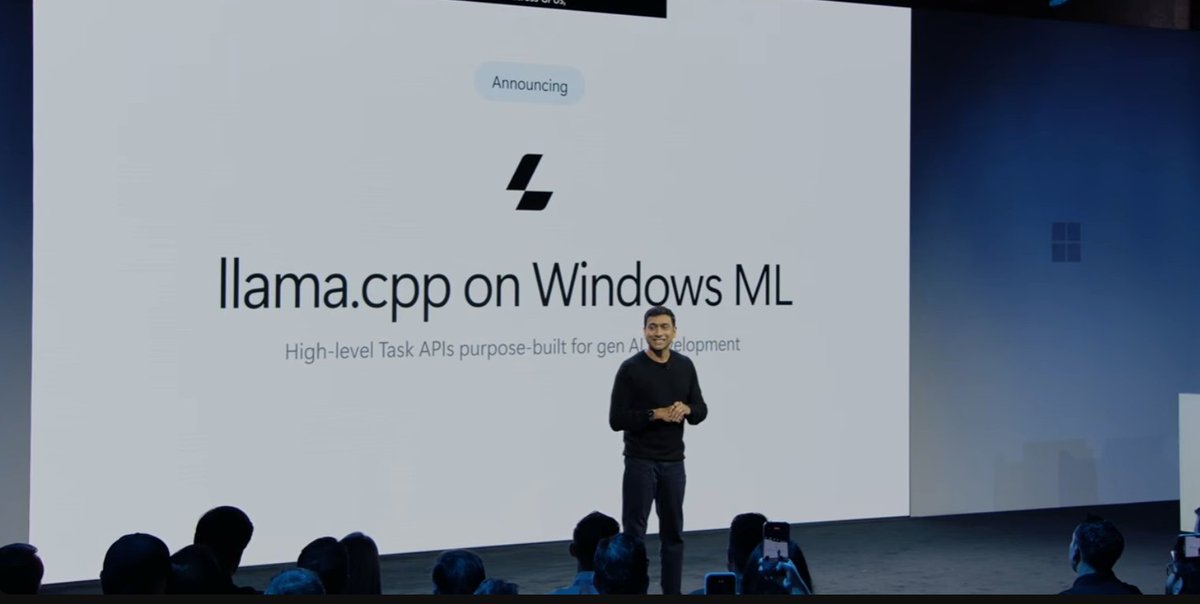 X · 19 days ago#4GGGeorgi Gerganov
It is very cool to see llama.cpp on the big stage in todays Windows event! The software and hardware stacks are finally coming together. Our community has put a lot of hard work in the past years and it shows. Looking…
33.8K views767 engagements
- X · 20 days ago#5
Day-0 support for EmbeddingGemma 2 in llama.cpp https://t.co/Gi4I3RNSXc
GGGeorgi Gerganov26.4K views703 engagements
- X · 19 days ago#6
llama.cpp can distribute inference on heterogeneous devices through the ggml RPC backend It's an advanced setting but I think with time we'll make it more accessible to regular users.
GGGeorgi Gerganov25.5K views532 engagements
Head-to-head