Top 100 IA · Estados Unidos
Sebastian Raschka
Independent 
- Score
- 8.9070 hoje
- Posição
- 7/198 ↓4
- em 90 dias
- −27−0,3%
Sebastian Raschka é um pesquisador de machine learning e IA especializado em grandes modelos de linguagem (LLMs). Ele é autor de vários livros, incluindo 'Construa um Grande Modelo de Linguagem do Zero', e possui vasta experiência tanto na academia quanto na indústria. Raschka compartilha insights técnicos, comparações arquiteturais e benchmarks de desempenho de LLMs em plataformas como Twitter, LinkedIn e YouTube.
Dados de 26 de out. de 2026.
Os números brutos · últimos 90 dias
- Visualizações medianas
- 251,2 mil
- por publicação
- Interações medianas
- 3,4 mil
- por publicação
- Publicações
- 74
- em 90 dias
- Seguidores
- 904,9 mil
- todas as redes pontuadas
O que compõe o score
Percentis 0 – 100 em relação a todos os criadores acompanhados.
- Alcance · 30%96
Média de visualizações por publicação em 90 dias
- Engajamento · 30%91
Média de reações por publicação
- Audiência · 30%95
Seguidores somados, em relação à população
- Regularidade · 10%100
Ritmo de publicação (25 posts / 90 d = 100)
Redes
904,9 mil seguidores somados
| Rede | Seguidores | Score |
|---|---|---|
| Instagram@sebastianraschka | 860 | 1.714t10 |
| YouTube@Sebastian Raschka | 100 mil | 6.480t4 |
| X@rasbt | 531 mil | 10.863t1 |
| LinkedIn@sebastianraschka | 273,1 mil | 8.700t1 |
| Threads@sebastianraschka | 6,9 mil | fora do score |
Últimos 30 dias
Os melhores posts de Raschka
 LinkedIn · há 28 dias#1SRSebastian Raschka
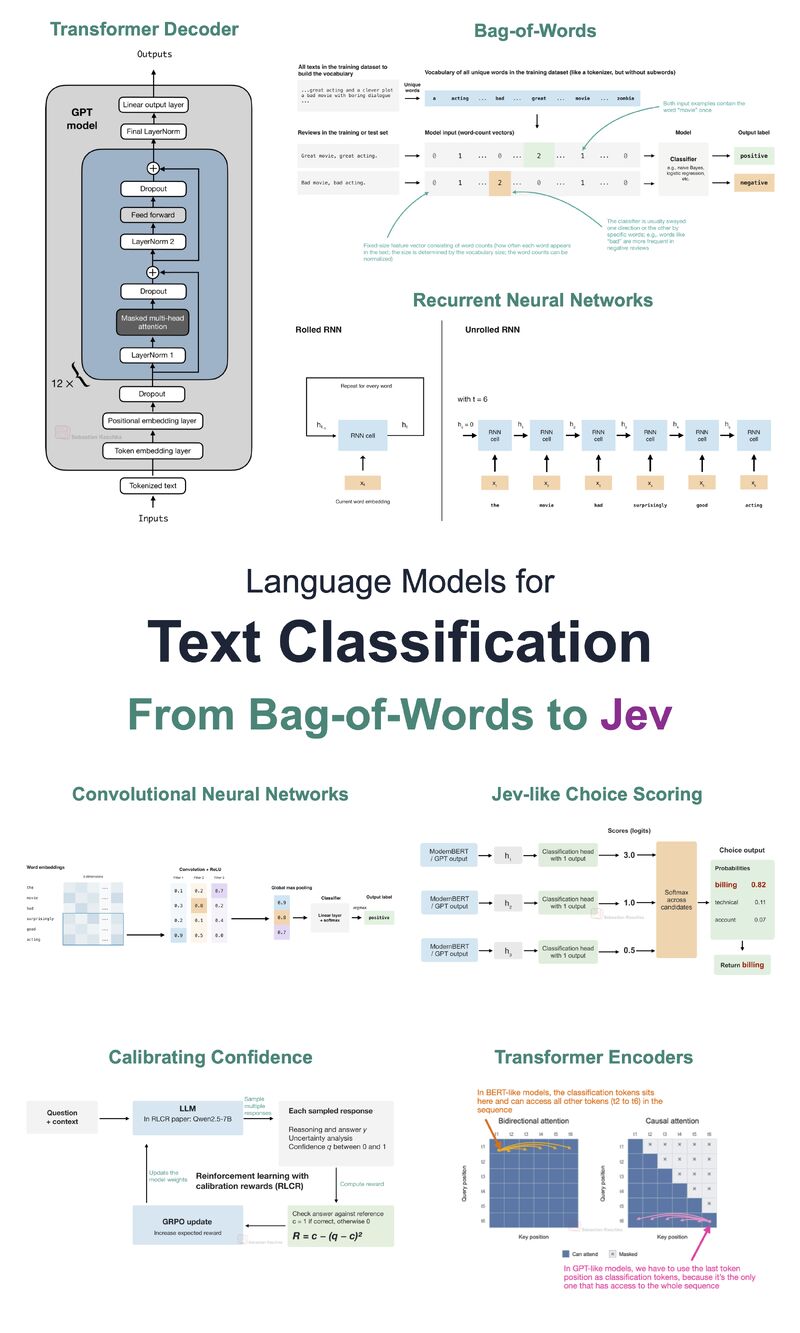
I just finished my new article on how language models for text classification and decision-making evolved, from bag-of-words to transformers and, of course, Jev. In particular, I am covering how various classic and co…
380,5 mil visualizações4,5 mil interações
 X · há 28 dias#2SRSebastian Raschka
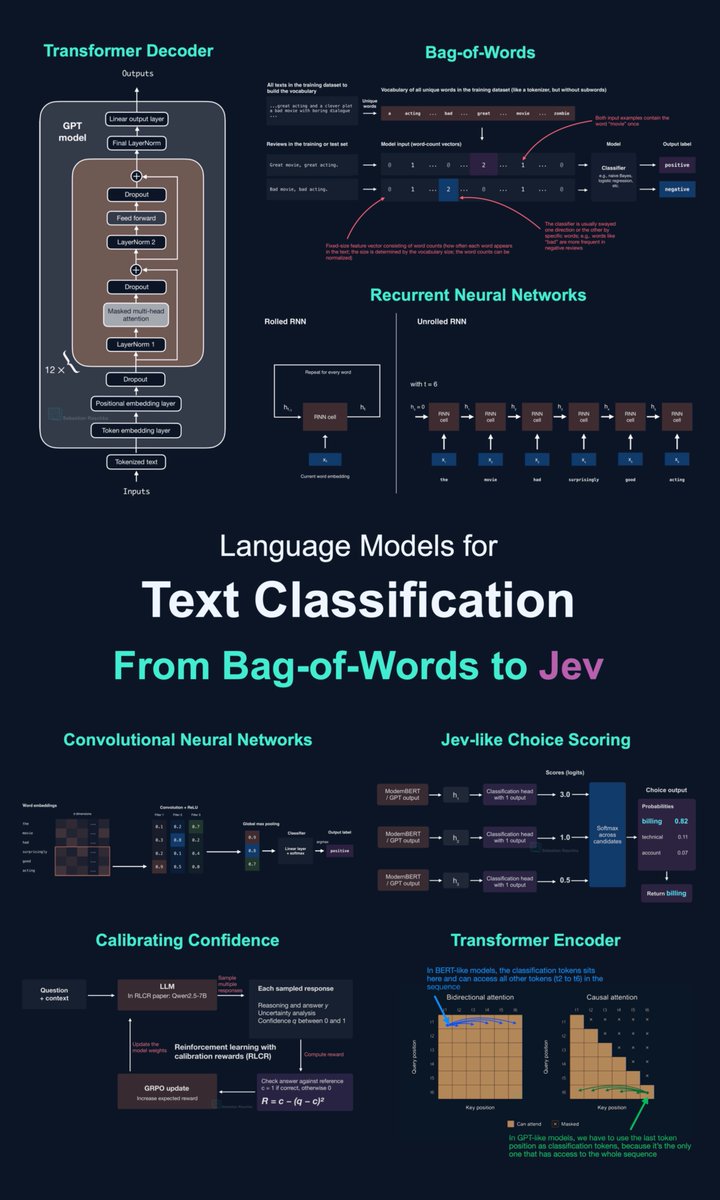
Took a while, but here it is, a mega write-up on language models for text classification and, of course, Jev. It's basically a visual guide to RNNs, CNNs, transformers, and calibration, with hands-on experiments on ac…
116,7 mil visualizações2,4 mil interações
 LinkedIn · anteontem#3SRSebastian Raschka
I've been a bit quiet last month, since I have been heads down building a reasoning model from-scratch lecture series, which is now complete! (8 coding videos with 11 hours of content total.) In my experience, impleme…
181,6 mil visualizações2,2 mil interações
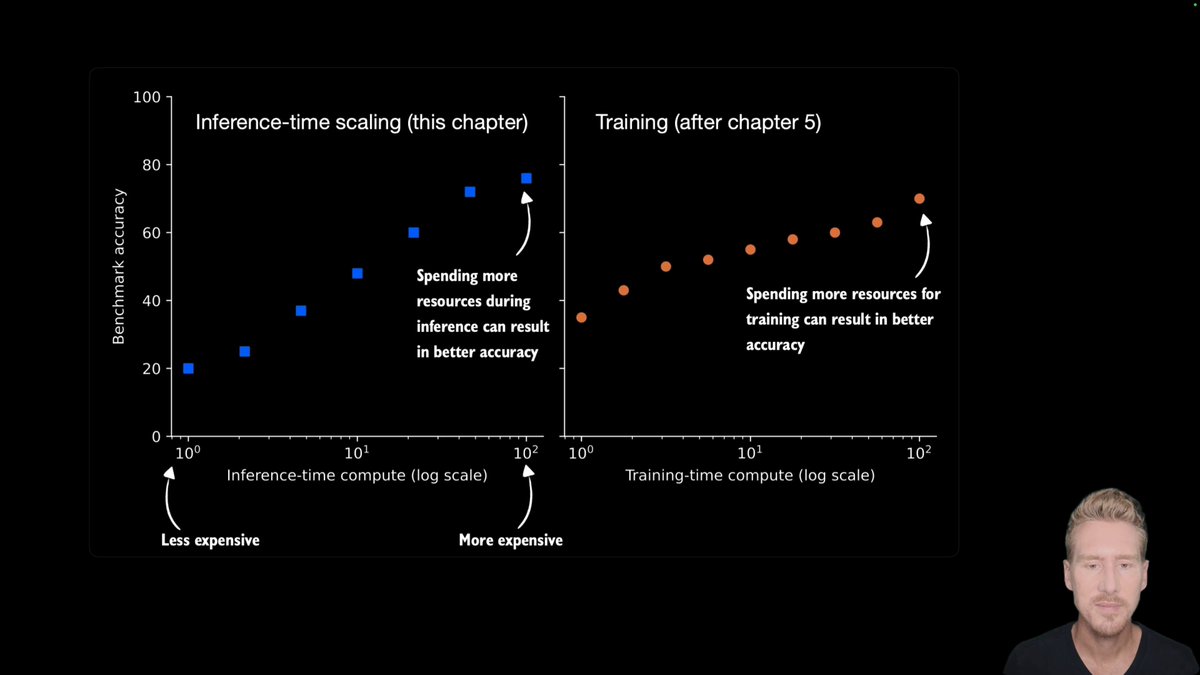 X · há 24 dias#4SRSebastian Raschka
Reasoning from scratch, round number 6! An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO). 00:00 Introduction 01:54 What makes …
74,7 mil visualizações1,7 mil interações
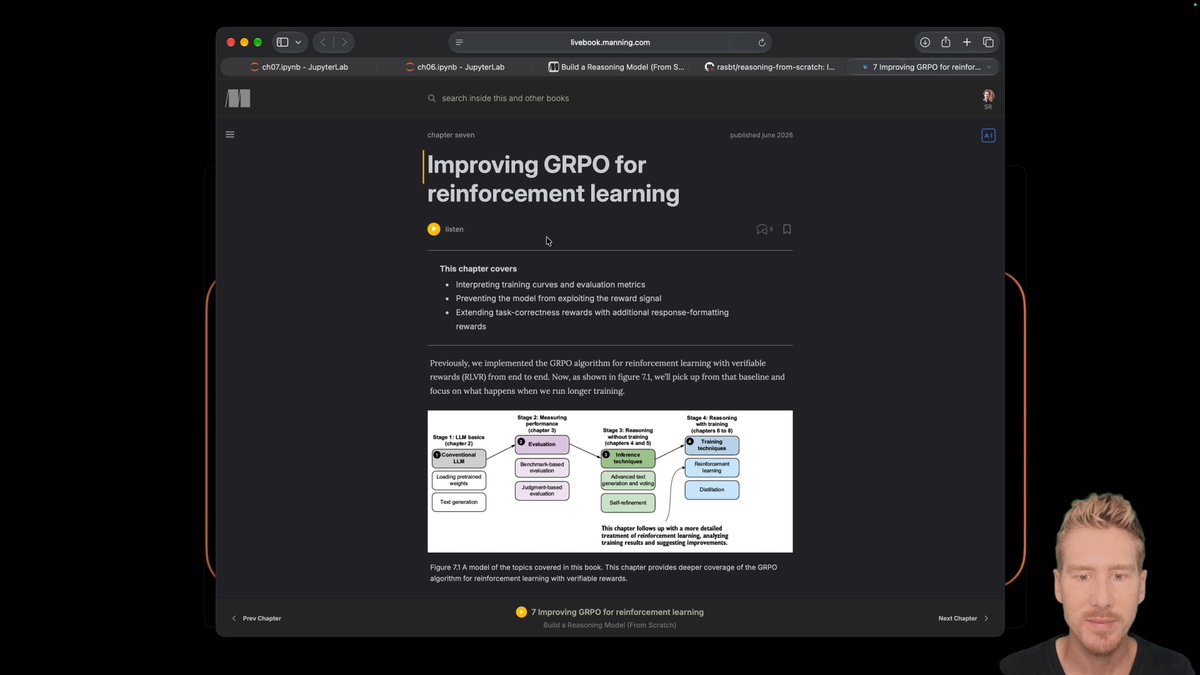 X · há 17 dias#5SRSebastian Raschka
Reasoning From Scratch: Reinforcement Learning with Verifiable Rewards (RLVR) round 2. Covering clipped policy ratios, KL loss term, format rewards, and other GRPO tips & tricks. 00:00 Introduction and recap 01:52…
58,2 mil visualizações1,3 mil interações
- X · anteontem#6
The complete reasoning-from-scratch video series is now up (and linked) here: https://t.co/5IOHLTCIGt (Taking a short break but will be back with LLM model and research updates in November!)
SRSebastian Raschka52,9 mil visualizações1,2 mil interações
Frente a frente