Top 100 AI · United States
Sebastian Raschka
Independent 
- Score
- 8,9070 today
- Rank
- 7/198 ↓4
- over 90 days
- −16−0.2%
Sebastian Raschka is a machine learning and AI researcher specializing in large language models (LLMs). He is the author of several books, including 'Build a Large Language Model From Scratch,' and has extensive experience in both academia and industry. Raschka shares technical insights, architectural comparisons, and performance benchmarks of LLMs across platforms like Twitter, LinkedIn, and YouTube.
Data as of Oct 25, 2026.
The raw numbers · last 90 days
- Median views
- 251.2K
- per post
- Median engagements
- 3.4K
- per post
- Posts
- 74
- over 90 days
- Followers
- 904.9K
- all scored platforms
What drives the score
Percentiles 0–100 against all tracked creators.
- Reach · 30%96
Average views per post over 90 days
- Engagement · 30%91
Average reactions per post
- Audience · 30%95
Total followers, relative to population
- Consistency · 10%100
Posting frequency (25 posts / 90 days = 100)
Platforms
904.9K total followers
| Platform | Followers | Score |
|---|---|---|
| Instagram@sebastianraschka | 860 | 1,714t10 |
| YouTube@Sebastian Raschka | 100K | 6,480t4 |
| X@rasbt | 531K | 10,863t1 |
| LinkedIn@sebastianraschka | 273.1K | 8,700t1 |
| Threads@sebastianraschka | 6.9K | not scored |
Last 30 days
Raschka's top posts
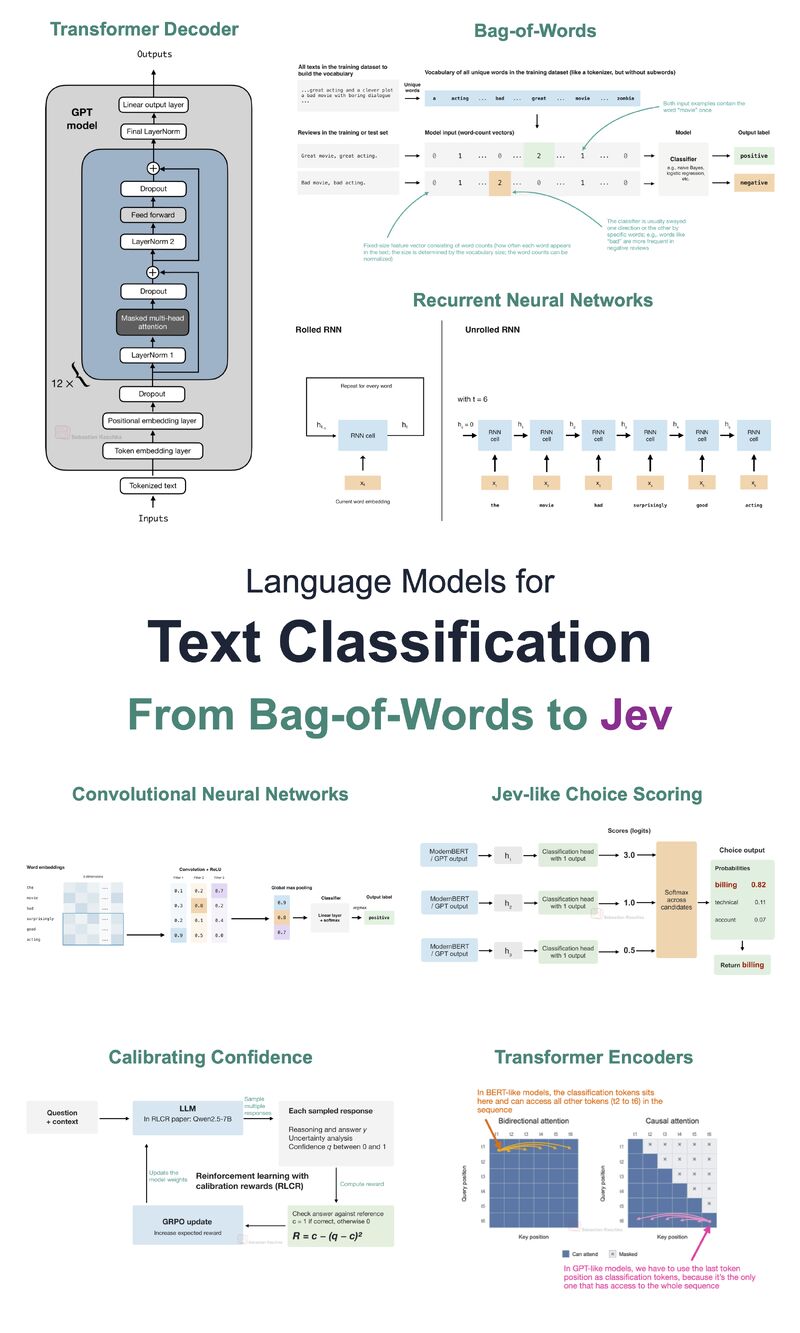 LinkedIn · 27 days ago#1SRSebastian Raschka
I just finished my new article on how language models for text classification and decision-making evolved, from bag-of-words to transformers and, of course, Jev. In particular, I am covering how various classic and co…
380.5K views4.5K engagements
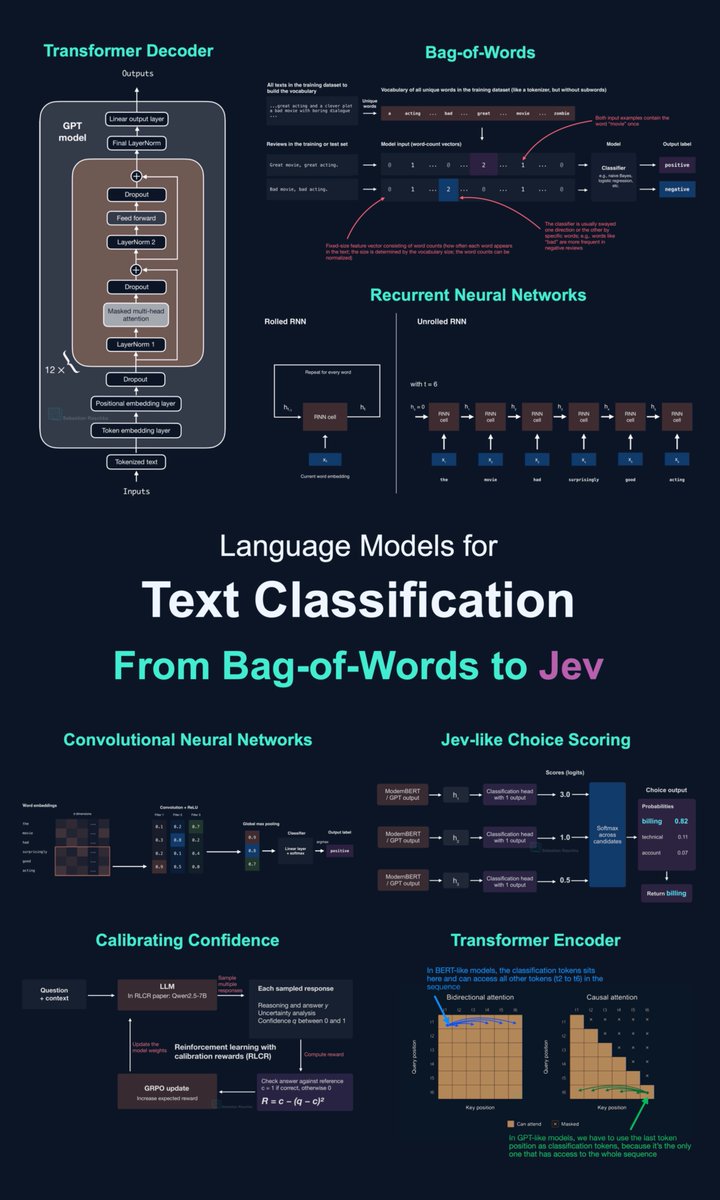 X · 27 days ago#2SRSebastian Raschka
Took a while, but here it is, a mega write-up on language models for text classification and, of course, Jev. It's basically a visual guide to RNNs, CNNs, transformers, and calibration, with hands-on experiments on ac…
116.7K views2.4K engagements
 LinkedIn · yesterday#3SRSebastian Raschka
I've been a bit quiet last month, since I have been heads down building a reasoning model from-scratch lecture series, which is now complete! (8 coding videos with 11 hours of content total.) In my experience, impleme…
181.6K views2.2K engagements
 X · 23 days ago#4SRSebastian Raschka
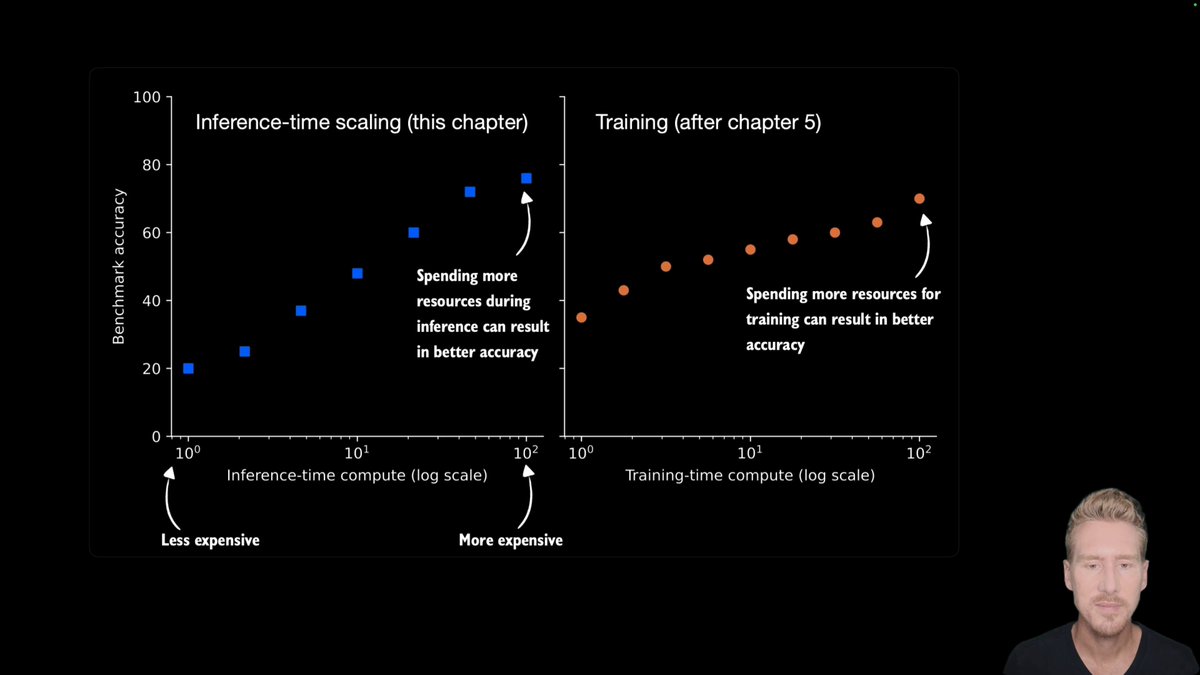
Reasoning from scratch, round number 6! An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO). 00:00 Introduction 01:54 What makes …
74.7K views1.7K engagements
 X · 16 days ago#5SRSebastian Raschka
Reasoning From Scratch: Reinforcement Learning with Verifiable Rewards (RLVR) round 2. Covering clipped policy ratios, KL loss term, format rewards, and other GRPO tips & tricks. 00:00 Introduction and recap 01:52…
58.2K views1.3K engagements
- X · yesterday#6
The complete reasoning-from-scratch video series is now up (and linked) here: https://t.co/5IOHLTCIGt (Taking a short break but will be back with LLM model and research updates in November!)
SRSebastian Raschka52.9K views1.2K engagements
Head-to-head