Top 100 IA · Francia
Maxime Labonne
Liquid AI 
- Puntuación
- 74590 hoy
- Puesto
- 64/198 ↓9
- en 90 días
- +143+1,8 %
Maxime Labonne es un científico especializado en aprendizaje automático, con foco en modelos de lenguaje grandes (LLMs) y redes neuronales de grafos. Es doctor por el Instituto Politécnico de París y está reconocido como Google Developer Expert en IA/aprendizaje automático. Labonne ha desarrollado varios LLMs populares, como AlpahMonarch-7B, Beyonder-4x7B, Phixtral y NeuralBeagle14, además de crear herramientas como LLM AutoEval y LazyMergekit.
Datos a 25 oct 2026.
Las cifras brutas · últimos 90 días
- Visualizaciones medianas
- 38,9 mil
- por publicación
- Interacciones medianas
- 490
- por publicación
- Publicaciones
- 97
- en 90 días
- Seguidores
- 120 mil
- todas las redes puntuadas
Qué compone la puntuación
Percentiles 0 – 100 frente a todos los creadores seguidos.
- Alcance · 30 %85
Visualizaciones medias por publicación en 90 días
- Interacción · 30 %72
Reacciones medias por publicación
- Audiencia · 30 %74
Seguidores acumulados, en relación con la población
- Regularidad · 10 %100
Ritmo de publicación (25 posts / 90 d = 100)
Redes
120 mil seguidores acumulados
| Red | Seguidores | Puntuación |
|---|---|---|
| X@maximelabonne | 44,7 mil | 8004t2 |
| LinkedIn@maxime-labonne | 75,2 mil | 11.182t1 |
Últimos 30 días
Las mejores publicaciones de Labonne
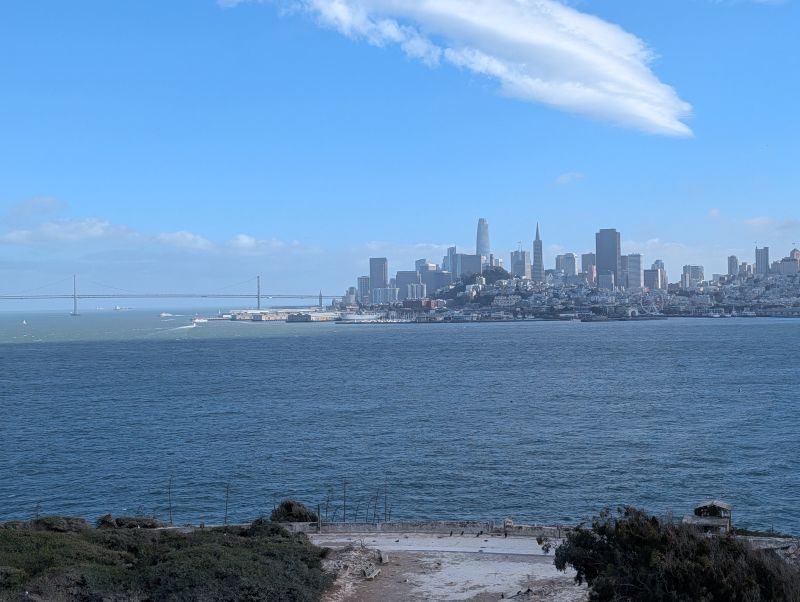 LinkedIn · hace 28 d#1ML
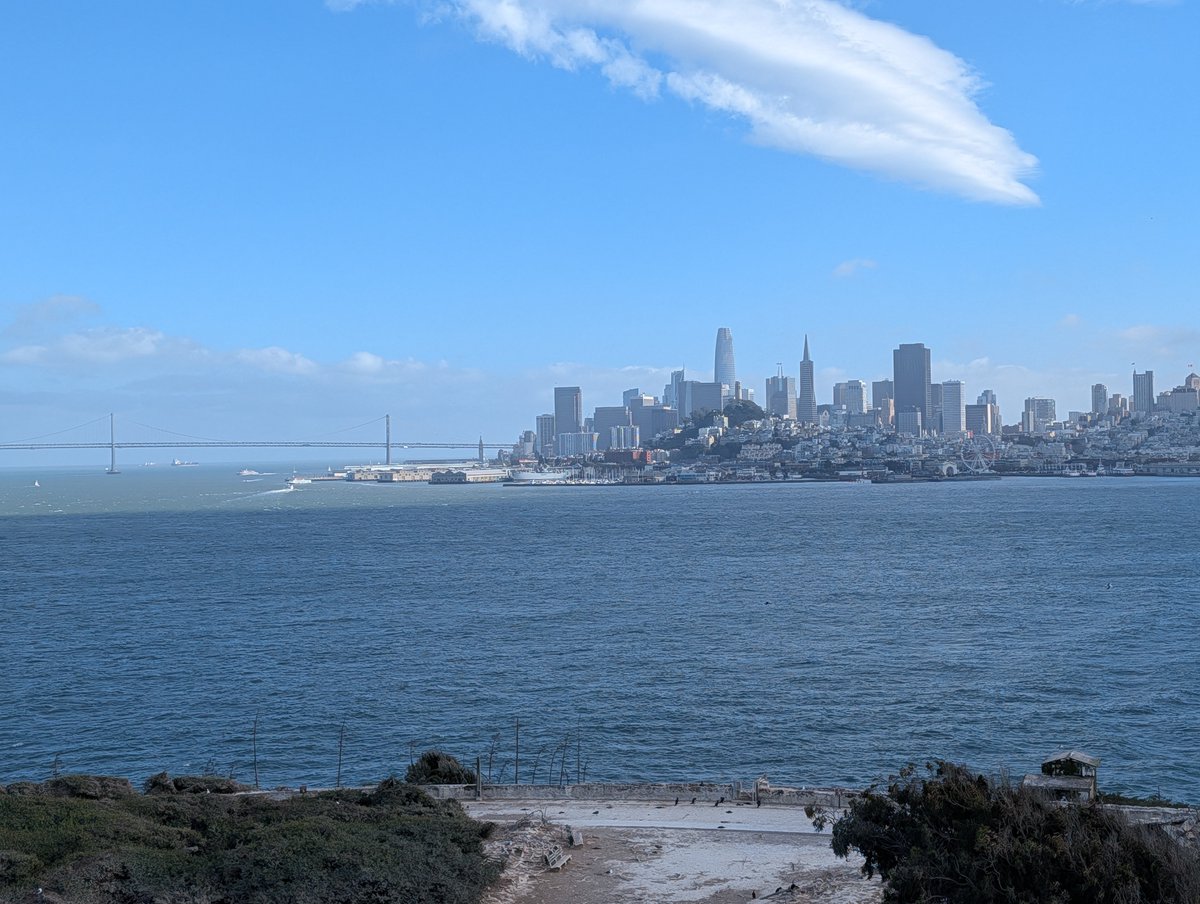
Goodbye London, hello San Francisco Life update: I moved to SF (with Liquid AI). It's quite nice to have an office after being fully remote for over two years. So far, the city is really pretty and the weather is actu…
80,8 mil visualizaciones1,1 mil interacciones
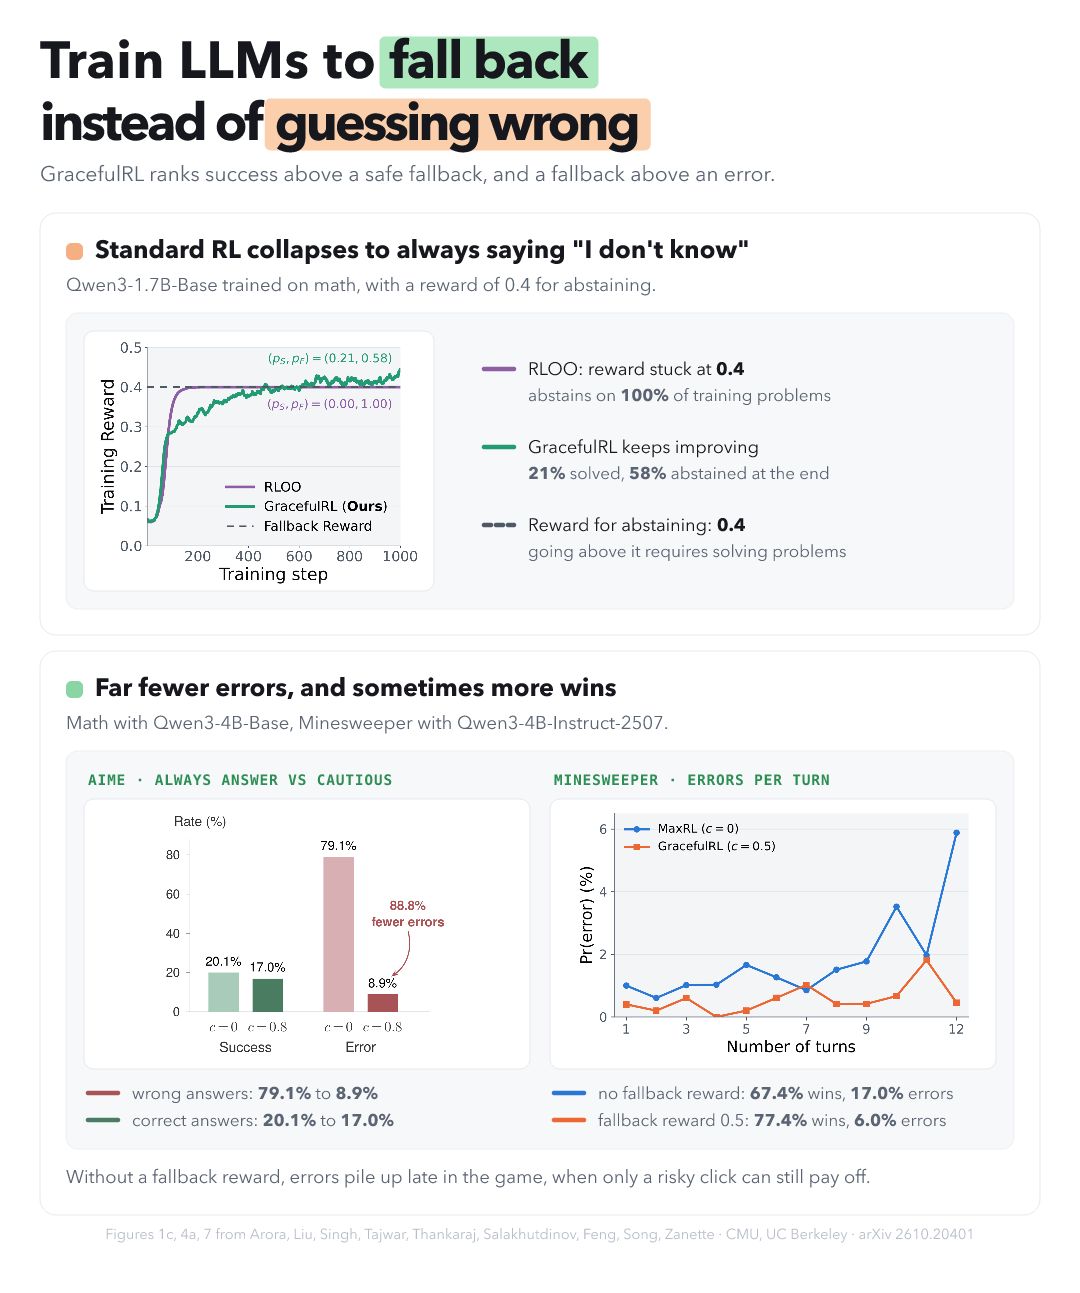 LinkedIn · hace 7 d#2ML
Can you train an LLM to say “I don’t know” without it saying it all the time? With reinforcement learning with verifiable rewards (RLVR), a model is rewarded for answering correctly. Saying "I don't know" is typically…
53,5 mil visualizaciones668 interacciones
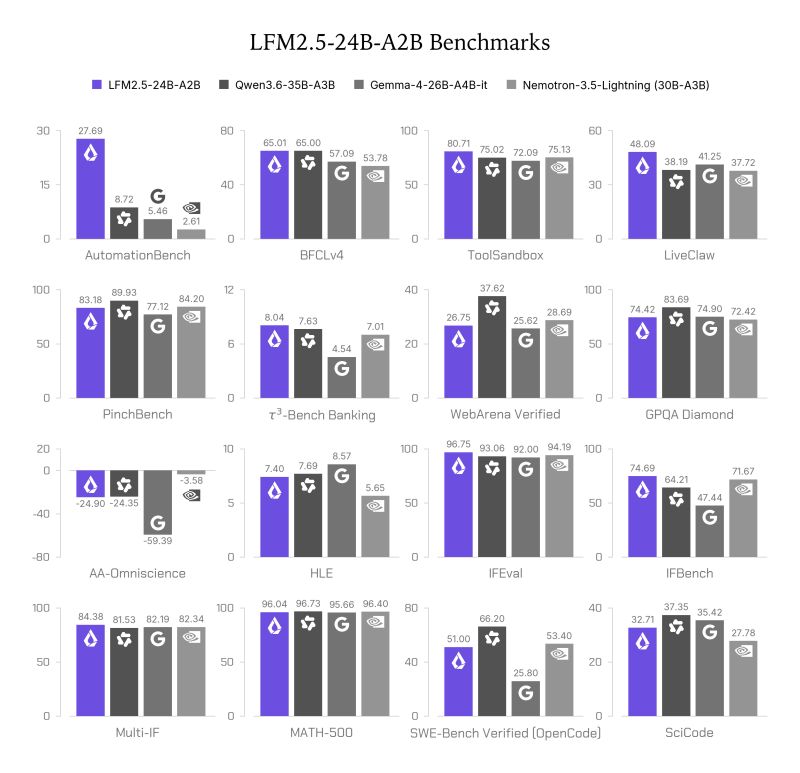 LinkedIn · hace 13 d#3ML
We just released LFM2.5-24B-A2B! 🥳 It's an extremely fast agentic model, competitive with models with 50% more parameters. We expanded the context window to 131k and training up to 36T tokens. On the post-training si…
53,1 mil visualizaciones661 interacciones
- X · hace 24 d#4
Great read: SFT generalizes worse than RL because the data is off-policy, not because of the SFT objective. Rewriting the trajectories from an expert to look like what the base model writes can match or beat on-policy…
ML41,9 mil visualizaciones620 interacciones
 X · hace 28 d#5ML
Life update: goodbye London, I moved to SF (still with @liquidai) 🫡 Let's grab coffee? https://t.co/bVgoyT9zJR
16,6 mil visualizaciones481 interacciones
 LinkedIn · hace 3 d#6ML
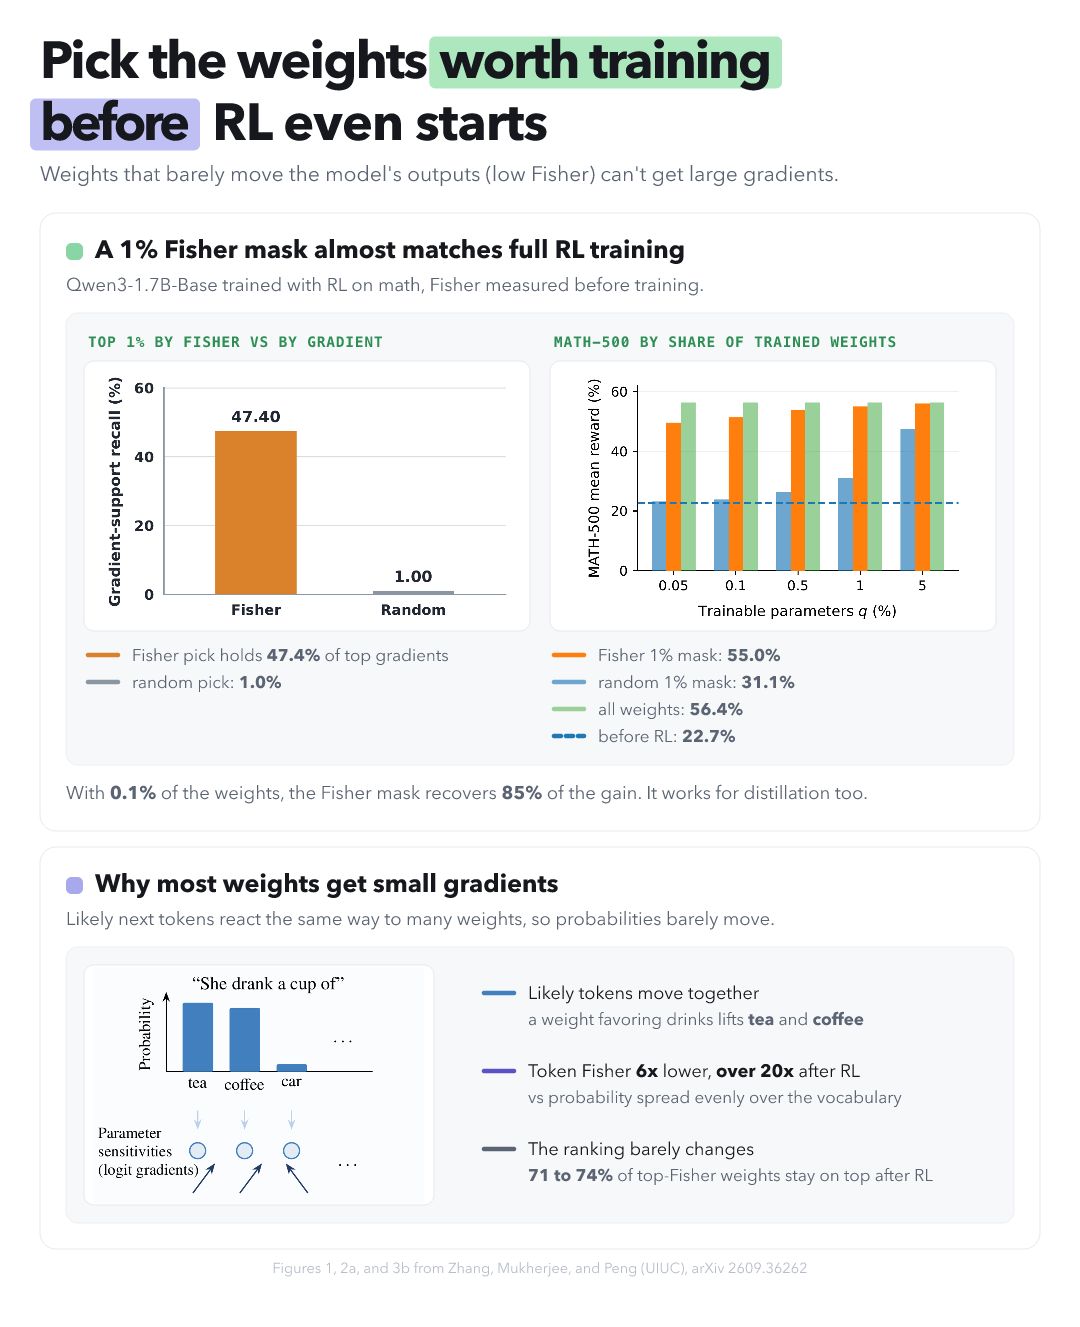
Understanding LLM Parameter Update Sparsity through the Lens of Fisher It's a cool paper that offers a competing explanation to the traditional "RL's updates are low rank because you get about 1 bit of information per…
30,6 mil visualizaciones366 interacciones
Cara a cara