Top 100 IA · Bulgarie
Georgi Gerganov
ggml 
- Score
- 7 201+1 auj.
- Rang
- 76/198 ↓6
- sur 90 jours
- +338+4,6 %
Georgi Gerganov est un physicien et programmeur reconnu pour ses contributions aux technologies open source et aux projets de programmation. Il se concentre sur le développement et la promotion d'outils comme llama.cpp, qui permettent une inférence locale efficace de l'IA. Son contenu comprend principalement des tutoriels techniques, des démonstrations de logiciels et des mises à jour sur les intégrations de modèles d'IA, collaborant souvent avec des organisations comme Hugging Face et NVIDIA.
Données au 26 oct. 2026.
Les chiffres bruts · 90 derniers jours
- Vues médianes
- 49,6 k
- par publication
- Interactions médianes
- 673
- par publication
- Publications
- 14
- sur 90 jours
- Abonnés
- 81 k
- tous réseaux scorés
Ce qui fait le score
Centiles 0 – 100 face à tous les créateurs suivis.
- Portée · 30 %87
Vues moyennes par publication sur 90 jours
- Engagement · 30 %77
Réactions moyennes par publication
- Audience · 30 %66
Abonnés cumulés, rapportés à la population
- Régularité · 10 %75
Rythme de publication (25 posts / 90 j = 100)
Réseaux
81 k abonnés cumulés
| Réseau | Abonnés | Score |
|---|---|---|
| YouTube@Georgi Gerganov | 3,4 k | 267t10 |
| X@ggerganov | 73,5 k | 9 616t1 |
| LinkedIn@georgi-gerganov-b230ab24 | 4,1 k | 837t10 |
30 derniers jours
Les meilleurs posts de Gerganov
- X · il y a 25 j#1
Decision models in llama.cpp are now available The `/v1/systemone` endpoint is available in the latest llama builds. Use it to do Jev-style inference locally, efficiently and privately. Multiple open models are suppor…
GGGeorgi Gerganov116,3 k vues2,4 k interactions
- X · il y a 22 j#2
The new v0.6.0 release packs a lot of good stuff: - Clef support (text + vision) - High-quality support for Qwen3.8-Flash-Next - Massive performance improvement with Metal - New `llama_batch_ext` API Also the website …
GGGeorgi Gerganov111,6 k vues933 interactions
- X · il y a 21 j#3
If you are using Qwen3.8-27B + MTP, make sure to upgrade to DFlash for extra speed: llama serve -hf ggml-org/Qwen3.8-27B-GGUF --spec-type draft-dflash --spec-draft-n-max 7 Requires the latest llama.cpp v0.6.0
GGGeorgi Gerganov43,5 k vues874 interactions
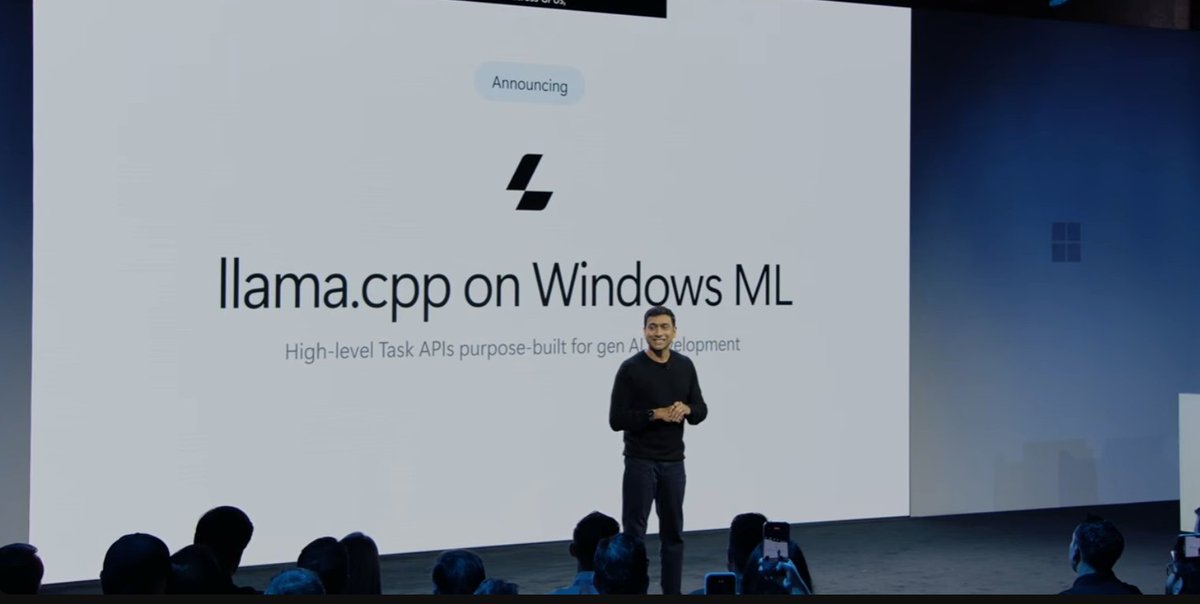 X · il y a 20 j#4GGGeorgi Gerganov
It is very cool to see llama.cpp on the big stage in todays Windows event! The software and hardware stacks are finally coming together. Our community has put a lot of hard work in the past years and it shows. Looking…
33,8 k vues767 interactions
- X · il y a 21 j#5
Day-0 support for EmbeddingGemma 2 in llama.cpp https://t.co/Gi4I3RNSXc
GGGeorgi Gerganov26,4 k vues703 interactions
- X · il y a 20 j#6
llama.cpp can distribute inference on heterogeneous devices through the ggml RPC backend It's an advanced setting but I think with time we'll make it more accessible to regular users.
GGGeorgi Gerganov25,5 k vues532 interactions
Face-à-face