Top 100 AI · United States
Horace He
Thinking Machines 
- Score
- 6,575+1 today
- Rank
- 103/198 ↓24
- over 90 days
- −225−3.1%
Horace He is a software engineer specializing in machine learning and compilers, with a focus on AI systems and human-AI interaction. He shares technical insights, performance comparisons, and educational content about ML models, hardware optimization, and coding solutions. His posts often include benchmarks, research findings, and memes related to AI and software engineering.
Data as of Oct 25, 2026.
The raw numbers · last 90 days
- Median views
- 27.9K
- per post
- Median engagements
- 243
- per post
- Posts
- 24
- over 90 days
- Followers
- 56K
- all scored platforms
What drives the score
Percentiles 0–100 against all tracked creators.
- Reach · 30%81
Average views per post over 90 days
- Engagement · 30%60
Average reactions per post
- Audience · 30%59
Total followers, relative to population
- Consistency · 10%98
Posting frequency (25 posts / 90 days = 100)
Platforms
56K total followers
| Platform | Followers | Score |
|---|---|---|
| X@chhillee | 54.9K | 7,984t2 |
| LinkedIn@horacehe | 1.1K | 35t10 |
Last 30 days
He's top posts
- X · 2 days ago#1
I'm doing DP. I'm doing TP. I'm doing SP. I'm doing PP. I'm doing ZP. I'm doing FSDP. I'm doing 1F1B. I'm doing CP. I'm doing ETP. I'm doing DPA. I'm doing VPP. I'm doing P/D. I'm doing ZBPP. I'm doing DPA. I'm doing …
HHHorace He41.8K views713 engagements
 X · 22 days ago#2HHHorace He
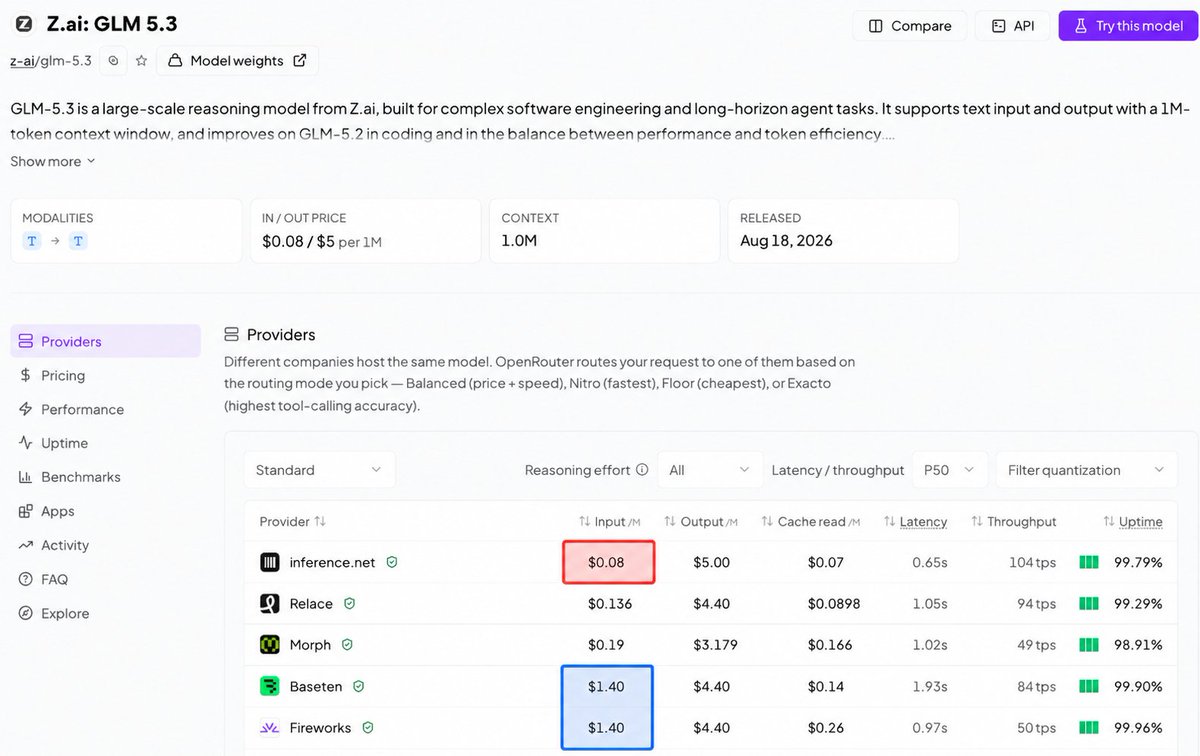
There's an interesting distortion in inference pricing that appears to be driven by openrouter's routing. Namely, ridiculously cheap prefill and very expensive decode. For GLM 5.3, https://t.co/aLgdvVsDHp (highest vol…
57.5K views686 engagements
- X · 8 days ago#3
Your model behaves differently during training and inference? Boy do I have a solution for you :^) https://t.co/60WkGyfwfD
HHHorace He30.2K views524 engagements
- X · 27 days ago#4
I find that surprisingly few people have *really* thought about why PD disagg is a good idea. Even fewer people have *really* thought about how PD disagg compares to mixed chunk prefill (as Matthew describes here).
HHHorace He113K views468 engagements
- X · 12 days ago#5
As @johnschulman2 has put it, there are many ways we can "spend compute to save our customers compute". Here's one of them - a variant of muon that works far better for lora fine-tuning :)
HHHorace He25.7K views329 engagements
- X · 30 days ago#6
I think this is kind of an interesting idea, and in some sense Tinker is already a way to "sell" our pretraining stack (although tinker admittedly doesn't use the super large scale features), but I'm not really sure w…
HHHorace He23.3K views248 engagements
Head-to-head